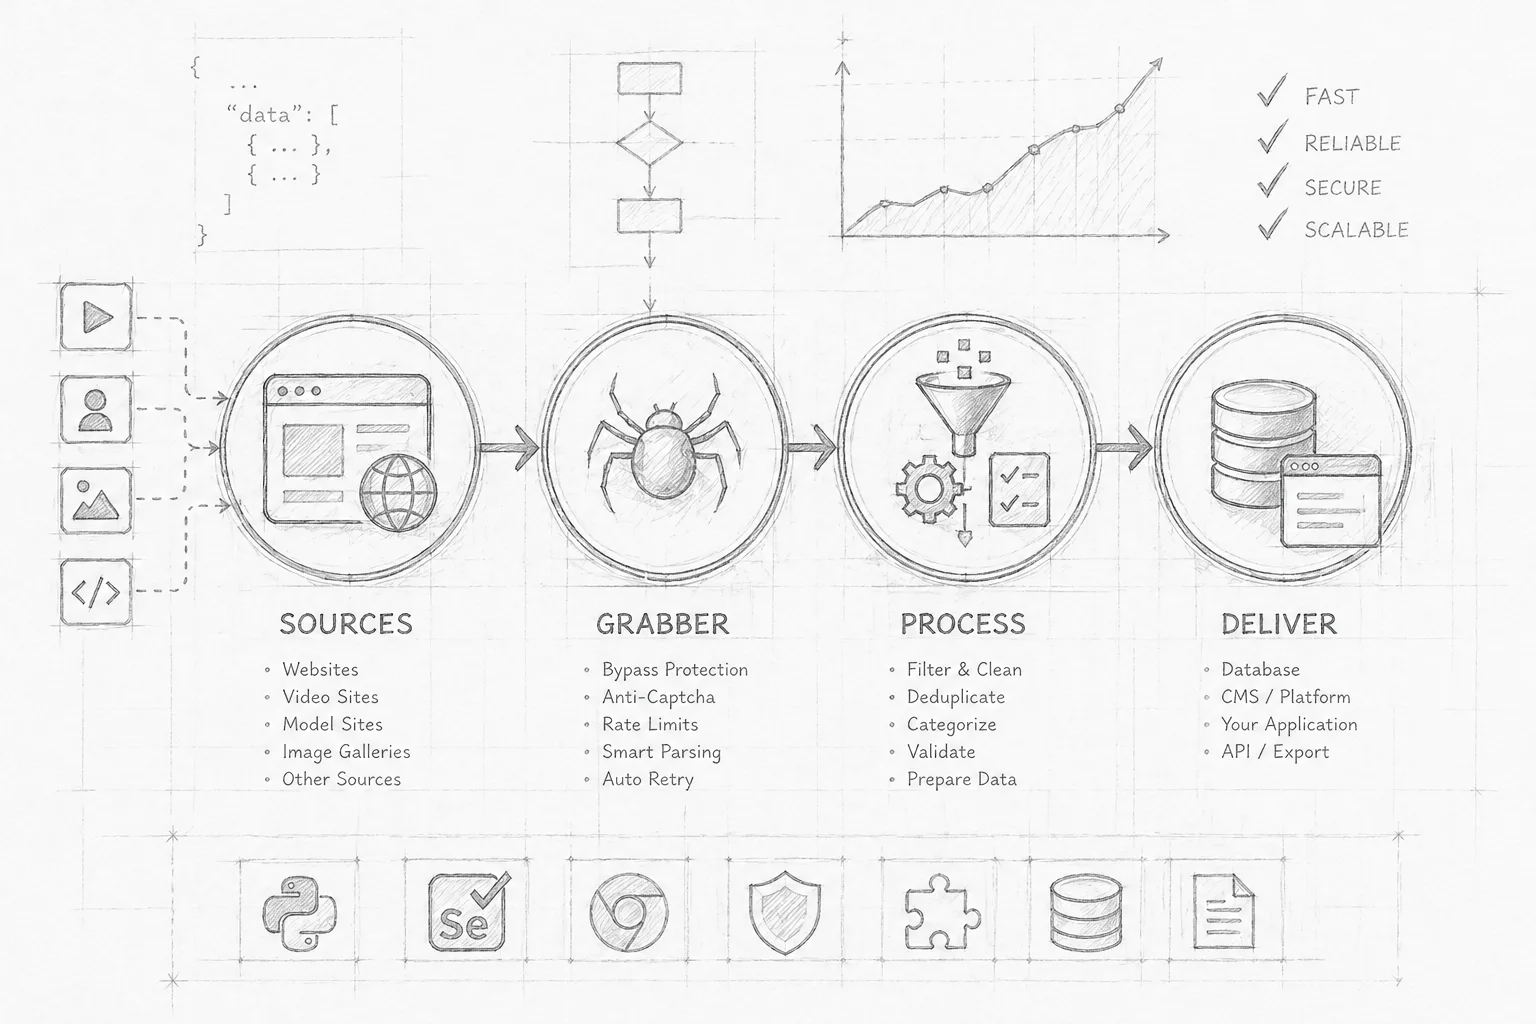
Scraper development for a specific site or group of sites, with the data structure in mind.
Support for different content types: video (including HLS/m3u8), images, albums, models, categories, tags, and descriptions.
Implemented as a CMS plugin (KVS, WordPress, DLE, and others) or as a standalone service on your server.
Collection, filtering, and storage logic configured to deliver data in the format you need.
Authenticated runs (login/password) and access to gated content where needed.
Base anti-bot handling: Cloudflare, anti-captcha, access restrictions.
Automation tooling (Python, Selenium, etc.) to mimic real user behavior when needed.
Testing and tuning for stable long-running operation.
Base support after hand-off (fixes when the source structure changes).
Duplicate-protection so content is never collected twice.
Run logging for error tracking and process control.
Base control panel or settings for flexible configuration (runs, filters, collection parameters).
Data processing and normalization before storage (cleanup, structure, formatting).